Reliable SaaS Workflows: What Matters Beyond the Dashboard
How state design, asynchronous processing, retries, observability and customer recovery shape the reliability of a production SaaS.
A polished dashboard is useful, but it does not make a SaaS product reliable. Real reliability comes from the decisions behind the interface: how a task starts, progresses, recovers, finishes and explains the result to the person waiting for it.
Consider a system that accepts an upload, processes it and prepares multiple outputs. The UI may show a progress bar, but the underlying workflow needs much more than a progress percentage.
1. Model the workflow as explicit states
Avoid treating every job as simply successful or failed. Real operations need distinguishable states, such as queued, validating, processing, finalizing, complete, retryable failure and permanent failure.
A state model should answer:
- What work has already succeeded?
- Which step can safely run next?
- Can the operation be resumed after a crash?
- Is the user allowed to cancel or retry?
- What should the UI tell the user right now?
Document the transitions and reject impossible combinations.
2. Separate the request from expensive work
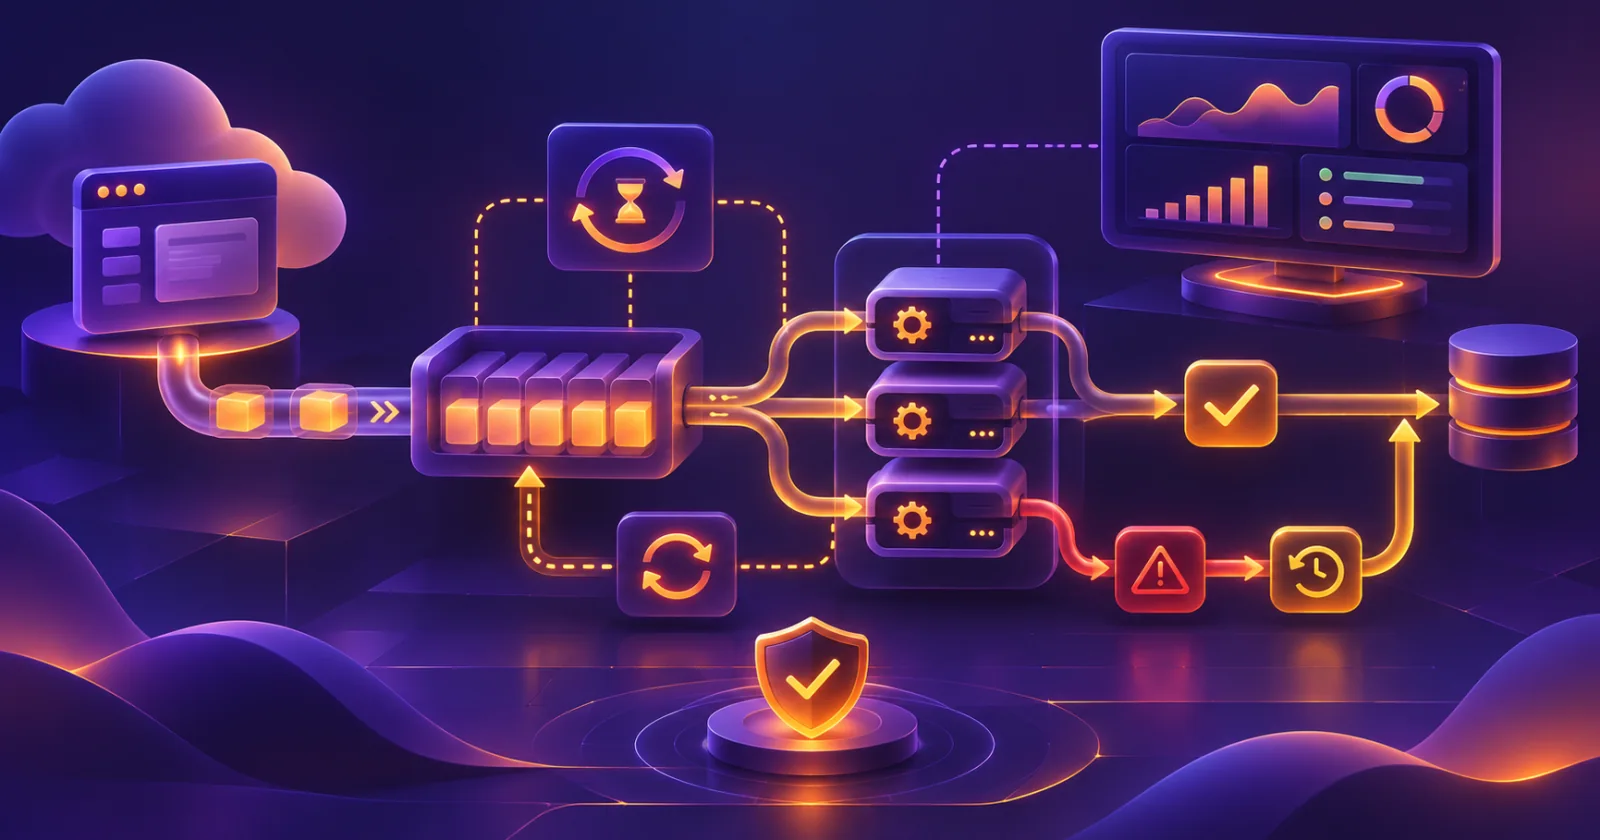
Long-running tasks should not depend on a browser tab staying open. Accept the request, validate it, persist a job record and process it through a worker or queue.
Return a stable job identifier so the client can retrieve progress later. The UI should gracefully handle refreshes, temporary network errors and delayed updates.
Do not report completion until final artifacts have passed the checks that matter to the customer.
3. Design for retries without duplicate results
Networks time out. Providers return errors. Workers can stop unexpectedly. Retrying is normal, but blindly repeating an action can create double charges, repeated emails or duplicate outputs.
Use idempotency keys for actions that must happen at most once from the customer's perspective. Record completed steps so the workflow can resume instead of restarting everything.
Classify errors into retryable and nonretryable cases. Add bounded retries with backoff rather than unlimited loops.
4. Make failures understandable
A generic "Something went wrong" message leaves both customers and support teams guessing. Keep the user-facing message concise and safe, but log enough operational detail to locate the failed step.
Useful internal signals include:
- Job ID and state transition history.
- Processing duration by stage.
- External API response categories and rate limits.
- Worker resource usage and queue wait time.
- Output validation results.
Never put secrets, access tokens or private customer content into logs by default.
5. Think about the slowest stage
A workflow's speed is shaped by the time spent waiting, transferring, processing and retrying—not only by CPU time.
Measure these stages separately. A faster worker will not solve a delay caused by large file transfers or a queue that starts jobs too late.
Use parallelism only where operations are independent, and keep capacity controls so one burst of traffic does not overwhelm the system.
6. Treat billing and recovery as core product behavior
If a paid operation fails, the system must have a clear policy: retry, refund a credit, allow manual recovery or escalate to support.
Payment webhooks should be verified and processed idempotently. Account entitlements should derive from trusted payment state, not from an unverified success page.
A customer should be able to see the status of recent jobs and understand what happens next.
7. Validate the final result
For media processing, confirm file integrity, duration, aspect ratio and deliverability. For generated reports, validate expected sections and data freshness. For integrations, confirm that the downstream side effect really occurred.
A successful API response is not always the same thing as a successful customer outcome.
8. Rehearse failure scenarios before launch
Test what happens if a worker restarts, an API rate limit is reached, an upload stops halfway or the customer refreshes during processing.
Also test duplicate requests, concurrent jobs, invalid inputs and partially completed work.
A production-readiness question
Before releasing a new workflow, ask: if the third step fails halfway through, can the system recover without losing work or misleading the user?
If you can explain and test that answer, you are much closer to an operationally reliable SaaS product.
Worked scenario: a job stops after one expensive stage succeeds
Consider a multi-step processing job: intake succeeds, a third-party service returns a result, and the worker crashes before the database records the next state. Restarting the entire workflow can waste compute or duplicate a charge. The system needs a durable checkpoint and safe retry policy.
- Assign an immutable job identifier and a separate identifier for any chargeable external action.
- Persist each successfully validated stage before allowing the next dependent stage to begin.
- Classify the crash as an unknown outcome until a reconciliation step establishes which side effects completed.
- Retry only the safe portion, with a bounded retry budget, backoff and jitter where appropriate.
- Surface a user-readable status that does not promise an output before final validation.
The objective is not to claim a distributed system will magically run every instruction exactly once. It is to make repeated delivery and uncertain outcomes safe for the business and predictable for the customer.
A practical production acceptance matrix
Before marking a workflow production-ready, test these conditions using synthetic jobs and a controlled environment:
- Duplicate request: Two identical submissions should not create two billable actions.
- Provider timeout: A timed-out call should not automatically be assumed to have failed on the provider side.
- Worker restart: Another worker must be able to resume from a durable state without replaying completed effects.
- Concurrent jobs: Limits and queue visibility must be observable under a short burst of load.
- Bad final artifact: A technically successful API response must still fail quality checks if the output is unusable.
- Customer recovery: The user should see a precise next action, including retry, support or credit restoration when applicable.
Instrument queue wait, execution duration by stage, retries, failure categories and outcome quality. Link logs, traces and metrics by job ID while keeping private content and secrets out of diagnostic output.
Real implementation: connected SaaS processing from upload to delivery
The [VidRango SaaS project](/projects/vidrango/) provides a concrete example of a connected, multi-stage processing workflow. The product brings together source upload, video preparation, captions, audio, reframing, destination-specific rendering and downloadable outputs. Its application and media stack includes Next.js, Node.js, PostgreSQL and FFmpeg.
The engineering value is in how these stages work together. A dependable system preserves the job state, keeps long-running media tasks out of the request/response cycle, coordinates workers and retries, and checks final files before users receive them. Each stage has a clear purpose: receive valid input, perform its task, record the outcome and hand off the correct state to the next stage.
For a buyer planning a SaaS platform, this translates into a practical implementation checklist:
- Workflow design: Define jobs, stages, allowed transitions, idempotency rules and customer-visible statuses.
- Backend orchestration: Connect the application database to processing workers, queues and third-party services.
- Recovery strategy: Resume safely from completed stages and apply bounded retries where appropriate.
- Operational visibility: Track queue time, processing duration, external service errors and stage-level status.
- Delivery validation: Confirm expected output formats, duration, integrity and download availability.
What to include in a production-ready handoff
A professional SaaS handoff includes the workflow diagram, processing-state model, retry rules, monitoring plan and acceptance tests. These are the assets that make a complex service understandable for customers and maintainable for an engineering team. Explore [VidRango's project overview](/projects/vidrango/) or [software development services](/services/) for related implementation context.
Further reading and related work
AWS documents bounded retries and exponential backoff and why queue consumers should be idempotent. The OpenTelemetry signal model provides a useful observability vocabulary. See [VidRango](/projects/vidrango/) for related SaaS product context or [software project examples](/projects/).
Explore my services and project work, or reach out with your specific challenge.
Discuss a project ↗